
Category
Benchmark
Real-world local-LLM benchmarks — tokens per second, prompt-processing, and VRAM fit — sourced from owners and our analysis.
October 10, 2026
ServeTheHome Tests a $100,000 DGX Station: 2.25 Billion Tokens a Day, and What It Means for One User
AI Mini PCs & Servers
September 13, 2026
AZisk's Quad RTX Pro 6000 Build: 384GB of VRAM, and 71% of Every Agent Turn Never Touches It
GPUs for Local LLM
September 12, 2026
Mac mini M4 (32GB) first-party benchmark: Qwen3 4B and 8B on llama.cpp, measured on our own machine
Unified-Memory AI
September 1, 2026
You Can Run DeepSeek V4 Flash on a Single RTX 3090. The Catch Is RAM, Not the GPU
GPUs for Local LLM
August 31, 2026
AZisk Bolted an RTX Pro 6000 Onto a Strix Halo and Ran a 122B Model Across NVIDIA and AMD at Once
AI Mini PCs & Servers
August 8, 2026
GMKtec EVO-X3 Tested by Wendell: The Fastest Strix Halo Yet, and Its Unholy OcuLink Trick
AI Mini PCs & Servers
August 1, 2026
DeepSeek V4 Flash Tested: Frontier-Class Coding for 79 Cents a Day, and It Runs on a 128GB Box
Open Models

July 13, 2026
A $1,000 Local-AI Server With 32GB of VRAM: Inside a Triple-3060 OptiPlex Build
GPUs for Local LLM
July 11, 2026
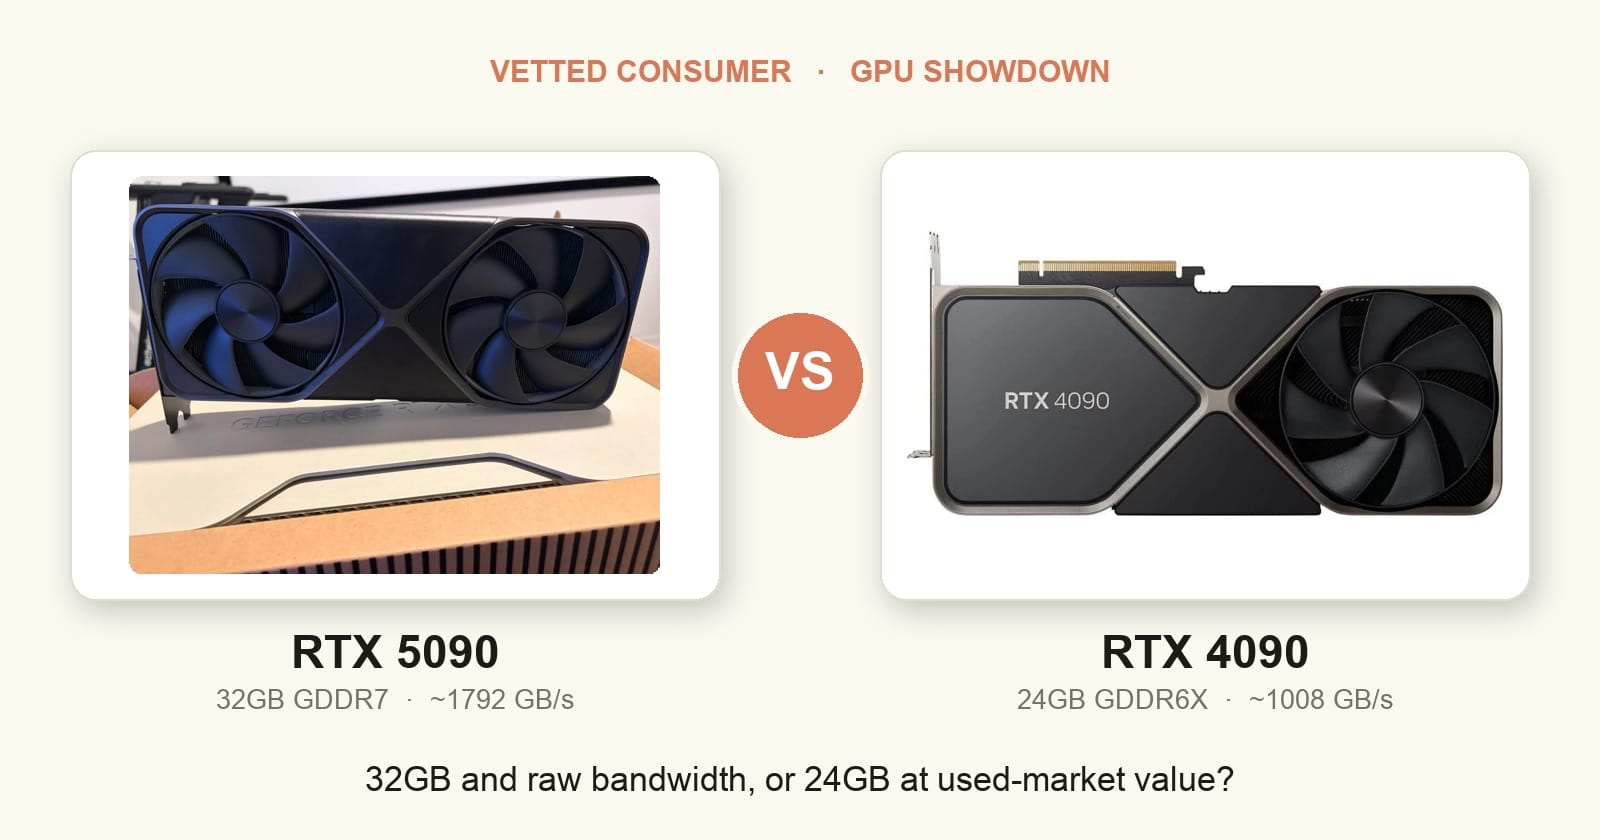
RTX 5090 vs RTX 4090 for Local LLMs: What 32GB and 78% More Bandwidth Really Buy
GPUs for Local LLM
June 30, 2026
Bandwidth, Not TFLOPS: What Sets Your Local LLM Speed (and Why the Newest Card Isn't Always Fastest)
GPUs for Local LLM

June 21, 2026
Three RTX 3060s vs One RTX 3090 for Local AI: What a $1,500 Build Actually Measured
GPUs for Local LLM
June 18, 2026
Beelink SER10 Max (Ryzen AI 9 HX 470): It “Caught” the M4 Pro, But Local-AI Buyers Should Read the Fine Print
AI Mini PCs & Servers
June 5, 2026
RTX 5090 vs RTX Pro 6000 for AI: A Benchmark Deep-Dive (and Why VRAM Wins)
GPUs for Local LLM