
Author
Thomas Newkirk
IT manager in Dayton, Ohio; editor of Vetted Consumer. I aggregate owner reports, lab tests and primary sources; numbers measured on my own Mac mini are labeled first-party. Non-commercial site.
July 4, 2026
Your Coral and Hailo TPU Can't Run an LLM. Here's Why (and What Hailo-10 Changed)
Edge AI & Accelerators
July 3, 2026
Raspberry Pi 5 (16GB) Buyer's Guide: A $120 Local-AI and Self-Hosting Machine
Edge AI & Accelerators
July 2, 2026
Unified Memory, Explained: Why Mini PCs Can Run 70B Models a Big GPU Can't (and Where They Slow Down)
AI Mini PCs & Servers
July 1, 2026
Three Mini PCs, One 70B Model: What Clustering Intel's New NUCs Can (and Can't) Do
AI Mini PCs & Servers
June 30, 2026
Bandwidth, Not TFLOPS: What Sets Your Local LLM Speed (and Why the Newest Card Isn't Always Fastest)
GPUs for Local LLM
June 29, 2026
GPT-5.6 is here, and you can't run it. Here's what you can run instead.
Open Models
June 26, 2026
Qwen-AgentWorld-35B-A3B: a local 'world model' you can run at home
Open Models
June 25, 2026
MiniMax M3: The First Open-Weight Multimodal Frontier Model (and the License Catch)
Open Models
June 21, 2026
Serving a Local LLM as an API: From Ollama's Endpoint to vLLM Throughput (and When to Rent Instead)
Software & Tools
June 21, 2026
Three RTX 3060s vs One RTX 3090 for Local AI: What a $1,500 Build Actually Measured
GPUs for Local LLM
June 20, 2026
Qwen3-30B-A3B: The Open Model Most People Should Actually Run
Open Models
June 20, 2026
Mac mini M4 Pro Buyer's Guide: Do You Actually Need the Pro?
AI Mini PCs & Servers
June 19, 2026
RAG on a Local LLM, Explained: Give Your Model Your Documents Without Drowning in Context
Software & Tools
June 18, 2026
GLM-5.2: The Most Powerful Open-Weight Model Yet, and the Brutal Reality of Running It Locally
Open Models
June 18, 2026
Beelink SER10 Max (Ryzen AI 9 HX 470): It “Caught” the M4 Pro, But Local-AI Buyers Should Read the Fine Print
AI Mini PCs & Servers
June 17, 2026
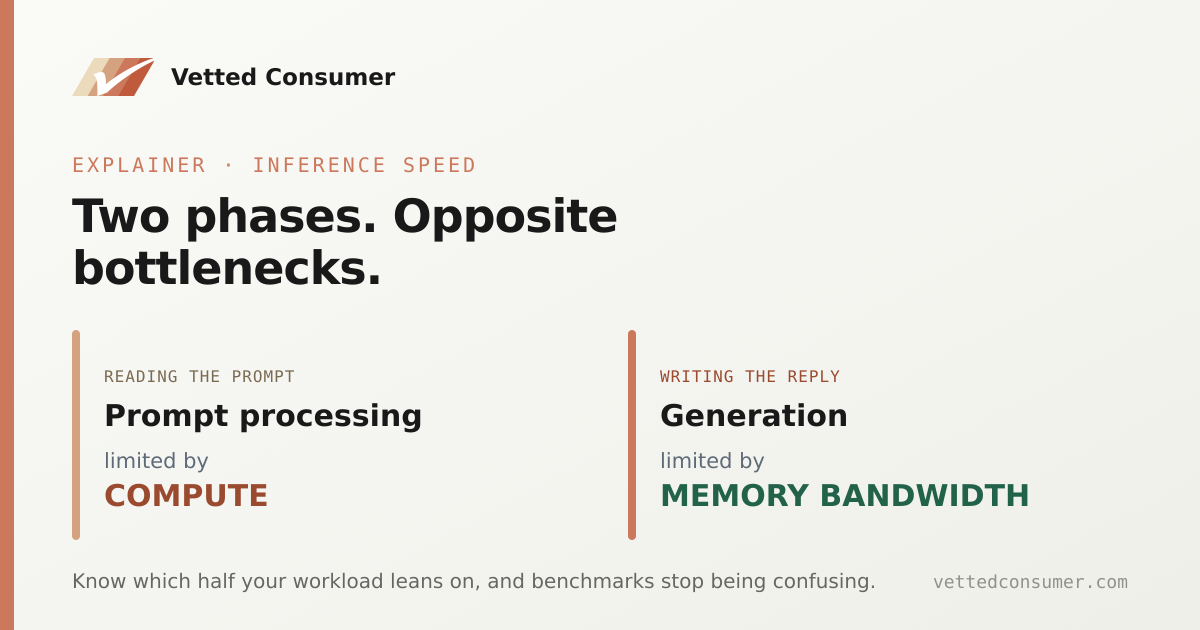
Prompt Processing vs Generation: Why Your Box Is Fast at One and Slow at the Other
Software & Tools
June 15, 2026
The KV Cache, Explained: Why Long Context Eats Your VRAM (and How to Fit More)
Software & Tools
June 15, 2026
The Local-LLM Hardware Cheat-Sheet: Which Box Runs Which Model
GPUs for Local LLM
June 14, 2026
The Used RTX 3090 in 2026: Why a Five-Year-Old GPU Is Still Local AI's Best Deal
GPUs for Local LLM
June 13, 2026
How Much VRAM Do You Actually Need to Run a 70B Model Locally?
Software & Tools
June 12, 2026
Ollama vs LM Studio vs llama.cpp: Which Local LLM Runtime Should You Actually Use?
Software & Tools
June 11, 2026
Mixture-of-Experts (MoE), Explained: Why “Active Parameters” Decide What Runs on Your Machine
Software & Tools
June 11, 2026
Your Local AI Model Folder Is a Mess: Taming a Multi-Terabyte Model Hoard on Apple Silicon
Unified-Memory AI
June 10, 2026
Mac Studio M3 Ultra vs DGX Spark for Local LLMs: What Owners of Both Measured
Unified-Memory AI
June 9, 2026
RTX 5090: A 32GB AI Powerhouse, or an Expensive Way to Game?
GPUs for Local LLM
June 8, 2026
RX 9060 XT 16GB Buyer's Guide: The Budget Value Champ (Buy the 16GB)
GPUs for Local LLM
June 6, 2026
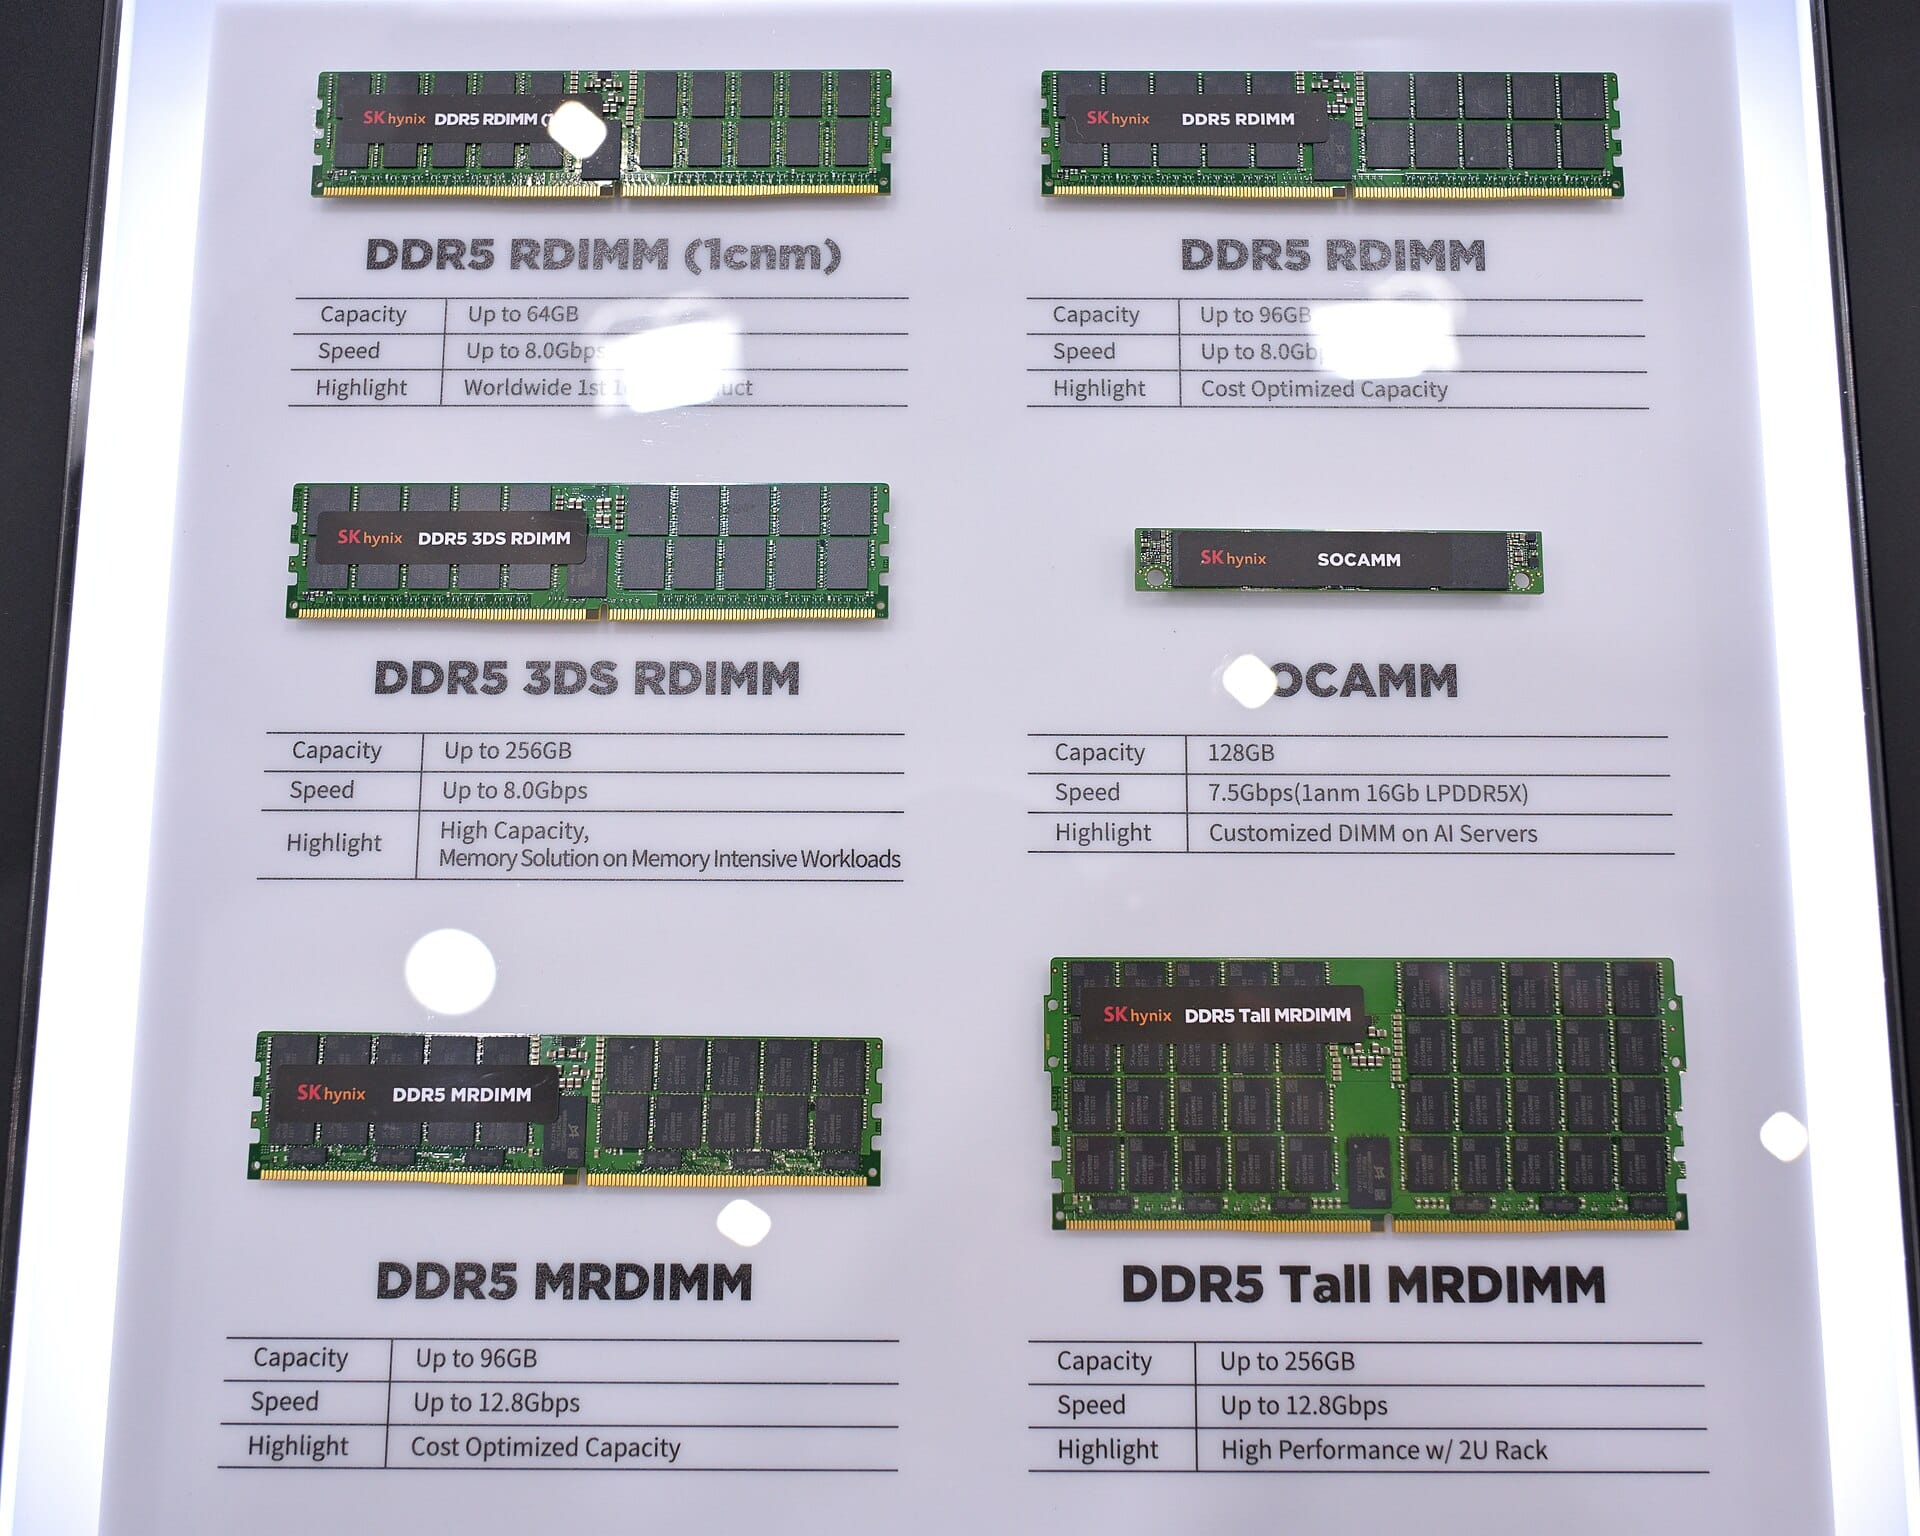
Why Everything Got More Expensive: The Memory Crisis, Explained (via Dave2D)
News
June 6, 2026
Strix Halo vs DGX Spark: Running 70B Locally, According to People Who Own Both
Unified-Memory AI
June 6, 2026
GGUF vs GPTQ vs AWQ: The Plain-English Guide to LLM Quantization (and Which One to Pick)
Software & Tools
June 6, 2026
Mac Studio M3 Ultra: The Local-AI Workhorse, Buy Now or Wait for M5?
Unified-Memory AI
June 5, 2026
Is the RTX Spark a 'Marketing Trap'? The Skeptic's Case (and What Owners Say)
Unified-Memory AI
June 5, 2026
Panther Lake's First Mini PC: Wendell Tests the MSI Cubi NUC AI+ (and What Owners Think)
AI Mini PCs & Servers
June 5, 2026
Framework Desktop Buyer's Guide: The Repairable Strix Halo Box That Runs 70B Models
Unified-Memory AI
June 5, 2026
GMKtec EVO-X2 Guide: The 128GB Mini PC That Runs 70B Models Locally
Unified-Memory AI
June 5, 2026
NVIDIA Jetson Orin Nano Super: The $249 Way Into Edge AI
Edge AI & Accelerators
June 5, 2026
Mac mini M4 Buyer's Guide: Is Apple's $599 Mini the Best-Value Mac?
AI Mini PCs & Servers
June 5, 2026
RTX 5090 vs RTX Pro 6000 for AI: A Benchmark Deep-Dive (and Why VRAM Wins)
GPUs for Local LLM
June 5, 2026
A Top Reviewer Put the Mac Studio M4 Max to the Test, Here's Who Should Actually Buy It
Unified-Memory AI
June 5, 2026
NVIDIA's RTX Spark Puts DGX-Class AI Silicon in a Laptop, Should You Wait?
Unified-Memory AI
June 3, 2026
The NVIDIA DGX Spark, According to the People Who Own One
Unified-Memory AI